Harden Kubernetes without breaking applications addresses a concrete operating problem: turn intent into verifiable behavior without hiding security, quality, or operational trade-offs. This piece moves from foundations to expert decisions, using a dedicated service account and security context matched to actual need as a running example and testing every choice against production constraints.
The real problem and scope
Harden Kubernetes without breaking applications becomes an engineering problem as soon as the system must remain dependable beyond a demo. The starting point is not the tool but the decision that needs protection: who may act, on which data, under which authority, and how the team can later prove what happened. The central angle here is cluster and workload hardening. The running example is a dedicated service account and security context matched to actual need, which keeps the discussion anchored in a concrete operating situation rather than an abstract architecture.
A robust design separates intent, state, execution, and evidence. Intent describes the business outcome; state records what the system actually knows; execution performs a bounded action; evidence makes that action reviewable. In Harden Kubernetes without breaking applications, this separation prevents a local error from becoming a system-wide inconsistency. It also improves testability because every boundary has an observable contract and an identifiable owner.
A beginner needs the nominal flow, but production engineering must examine deviations: ambiguous input, missing data, unavailable dependencies, network retries, duplicates, insufficient permission, or contradictory results. Each case needs an explicit response. The right behavior is not always to retry. Sometimes the safe choice is to refuse, queue, request approval, or preserve state for an idempotent recovery.
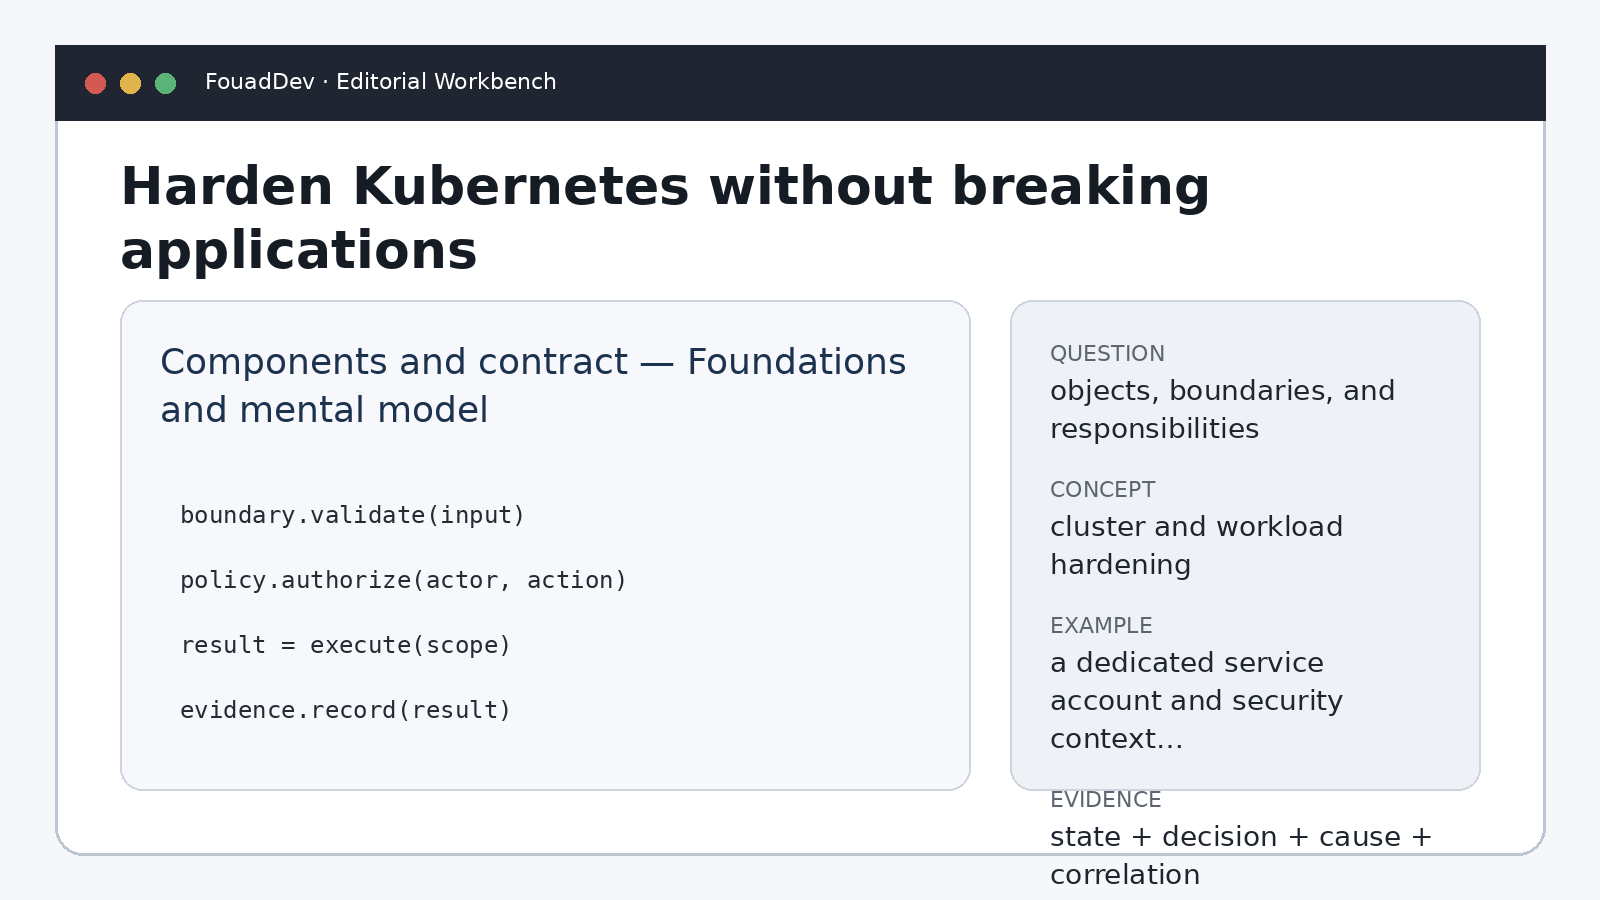
At the intermediate level, those rules become explicit interfaces. Inputs are validated before sensitive components are called; outputs are checked before they are persisted or propagated; external dependencies are wrapped behind stable boundaries. This lowers coupling and makes incremental evolution possible. A team can replace an implementation without rewriting the entire business journey when the contract remains stable and regression-tested.
Foundations and mental model
Advanced practice is mostly about observability and risk control. Logs should carry correlation identifiers, the minimum useful context, the decision taken, and the cause of failure without exposing unnecessary sensitive data. Metrics and traces are not substitutes for business reasoning. They should answer operational questions such as where the flow stopped, whether a retry is safe, and which component owns the next action.
In practice, a dedicated service account and security context matched to actual need must be testable end to end. Prepare a nominal case, incomplete data, an authorization denial, an unavailable dependency, and a repeated request. Define the expected result before running each test. This turns requirements into evidence and avoids validation that relies only on a screen looking correct or on the absence of an exception.
The main trade-off often sits between immediate simplicity and future controllability. A queue, guardrail, approval gate, or additional layer has a cost. That cost is justified when failures are hard to detect, expensive to reverse, or capable of affecting people, data, or critical operations. Adding components without a matching risk, however, increases the failure surface and cognitive load.
An expert pitfall is to confuse automation with autonomy. Automating a known sequence is different from delegating an open-ended decision. For Harden Kubernetes without breaking applications, define what may execute automatically, what requires a deterministic policy, and what needs human confirmation. That classification should be visible in code, tests, and operating procedures rather than living only in a high-level document.
Architecture and structural decisions
A production review should therefore look for concrete evidence: versioned contracts, regression tests, error handling, privilege controls, useful logging, a recovery strategy, and a clearly named owner. A feature may look successful in a demonstration and still be unoperable if the team cannot diagnose failure or restore a coherent state.
Quality ultimately shows up in the system's ability to make decisions understandable. An operator should distinguish an intentional refusal from an outage, a waiting state from lost data, and a legitimate retry from a duplicate. That operational legibility is an architectural outcome. It shortens diagnosis and prevents manual fixes from hiding a structural defect.
Harden Kubernetes without breaking applications becomes an engineering problem as soon as the system must remain dependable beyond a demo. The starting point is not the tool but the decision that needs protection: who may act, on which data, under which authority, and how the team can later prove what happened. The central angle here is cluster and workload hardening. The running example is a dedicated service account and security context matched to actual need, which keeps the discussion anchored in a concrete operating situation rather than an abstract architecture.
A robust design separates intent, state, execution, and evidence. Intent describes the business outcome; state records what the system actually knows; execution performs a bounded action; evidence makes that action reviewable. In Harden Kubernetes without breaking applications, this separation prevents a local error from becoming a system-wide inconsistency. It also improves testability because every boundary has an observable contract and an identifiable owner.
Implementation and expected evidence
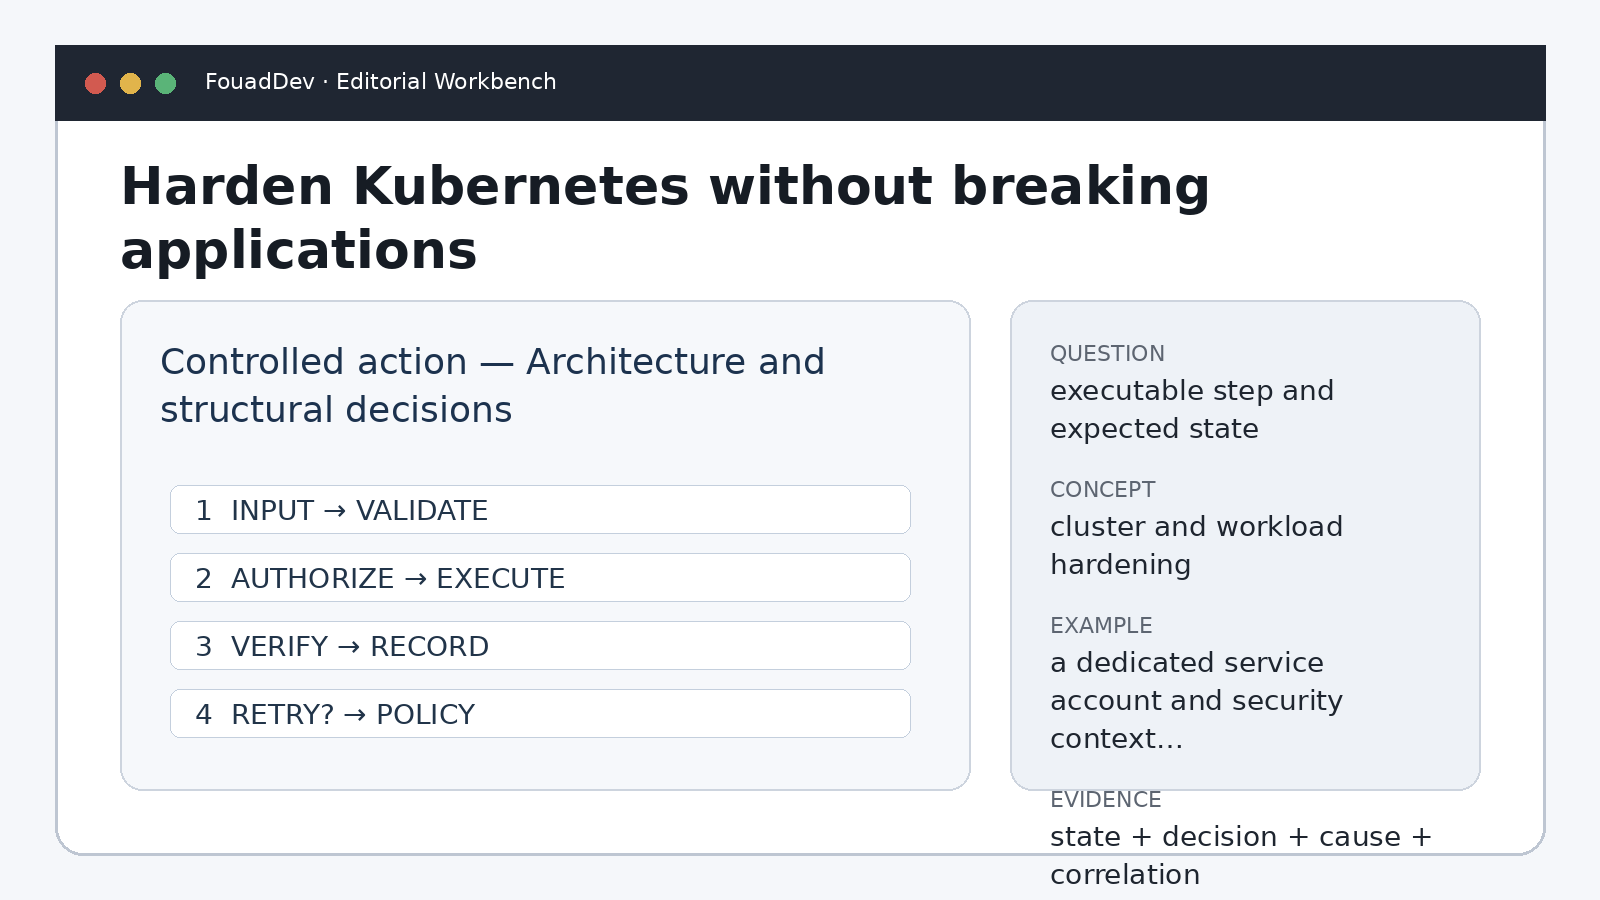
A beginner needs the nominal flow, but production engineering must examine deviations: ambiguous input, missing data, unavailable dependencies, network retries, duplicates, insufficient permission, or contradictory results. Each case needs an explicit response. The right behavior is not always to retry. Sometimes the safe choice is to refuse, queue, request approval, or preserve state for an idempotent recovery.
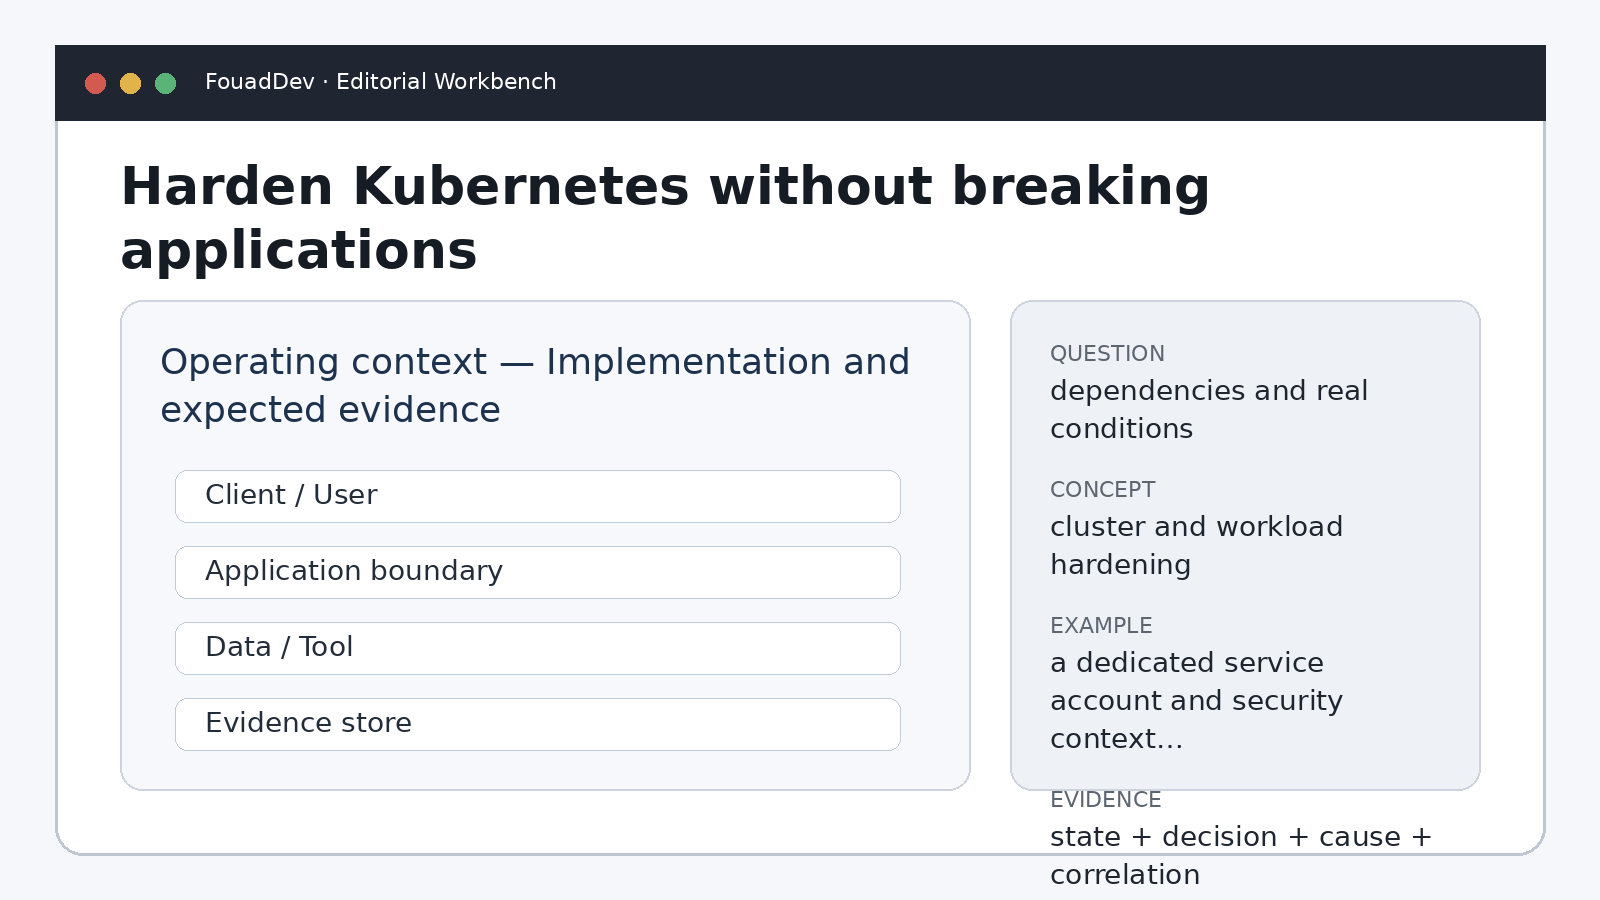
At the intermediate level, those rules become explicit interfaces. Inputs are validated before sensitive components are called; outputs are checked before they are persisted or propagated; external dependencies are wrapped behind stable boundaries. This lowers coupling and makes incremental evolution possible. A team can replace an implementation without rewriting the entire business journey when the contract remains stable and regression-tested.
Advanced practice is mostly about observability and risk control. Logs should carry correlation identifiers, the minimum useful context, the decision taken, and the cause of failure without exposing unnecessary sensitive data. Metrics and traces are not substitutes for business reasoning. They should answer operational questions such as where the flow stopped, whether a retry is safe, and which component owns the next action.
In practice, a dedicated service account and security context matched to actual need must be testable end to end. Prepare a nominal case, incomplete data, an authorization denial, an unavailable dependency, and a repeated request. Define the expected result before running each test. This turns requirements into evidence and avoids validation that relies only on a screen looking correct or on the absence of an exception.
Production trade-offs and operations
The main trade-off often sits between immediate simplicity and future controllability. A queue, guardrail, approval gate, or additional layer has a cost. That cost is justified when failures are hard to detect, expensive to reverse, or capable of affecting people, data, or critical operations. Adding components without a matching risk, however, increases the failure surface and cognitive load.
An expert pitfall is to confuse automation with autonomy. Automating a known sequence is different from delegating an open-ended decision. For Harden Kubernetes without breaking applications, define what may execute automatically, what requires a deterministic policy, and what needs human confirmation. That classification should be visible in code, tests, and operating procedures rather than living only in a high-level document.
A production review should therefore look for concrete evidence: versioned contracts, regression tests, error handling, privilege controls, useful logging, a recovery strategy, and a clearly named owner. A feature may look successful in a demonstration and still be unoperable if the team cannot diagnose failure or restore a coherent state.
Quality ultimately shows up in the system's ability to make decisions understandable. An operator should distinguish an intentional refusal from an outage, a waiting state from lost data, and a legitimate retry from a duplicate. That operational legibility is an architectural outcome. It shortens diagnosis and prevents manual fixes from hiding a structural defect.
Expert pitfalls and failure modes
Harden Kubernetes without breaking applications becomes an engineering problem as soon as the system must remain dependable beyond a demo. The starting point is not the tool but the decision that needs protection: who may act, on which data, under which authority, and how the team can later prove what happened. The central angle here is cluster and workload hardening. The running example is a dedicated service account and security context matched to actual need, which keeps the discussion anchored in a concrete operating situation rather than an abstract architecture.
A robust design separates intent, state, execution, and evidence. Intent describes the business outcome; state records what the system actually knows; execution performs a bounded action; evidence makes that action reviewable. In Harden Kubernetes without breaking applications, this separation prevents a local error from becoming a system-wide inconsistency. It also improves testability because every boundary has an observable contract and an identifiable owner.
A beginner needs the nominal flow, but production engineering must examine deviations: ambiguous input, missing data, unavailable dependencies, network retries, duplicates, insufficient permission, or contradictory results. Each case needs an explicit response. The right behavior is not always to retry. Sometimes the safe choice is to refuse, queue, request approval, or preserve state for an idempotent recovery.
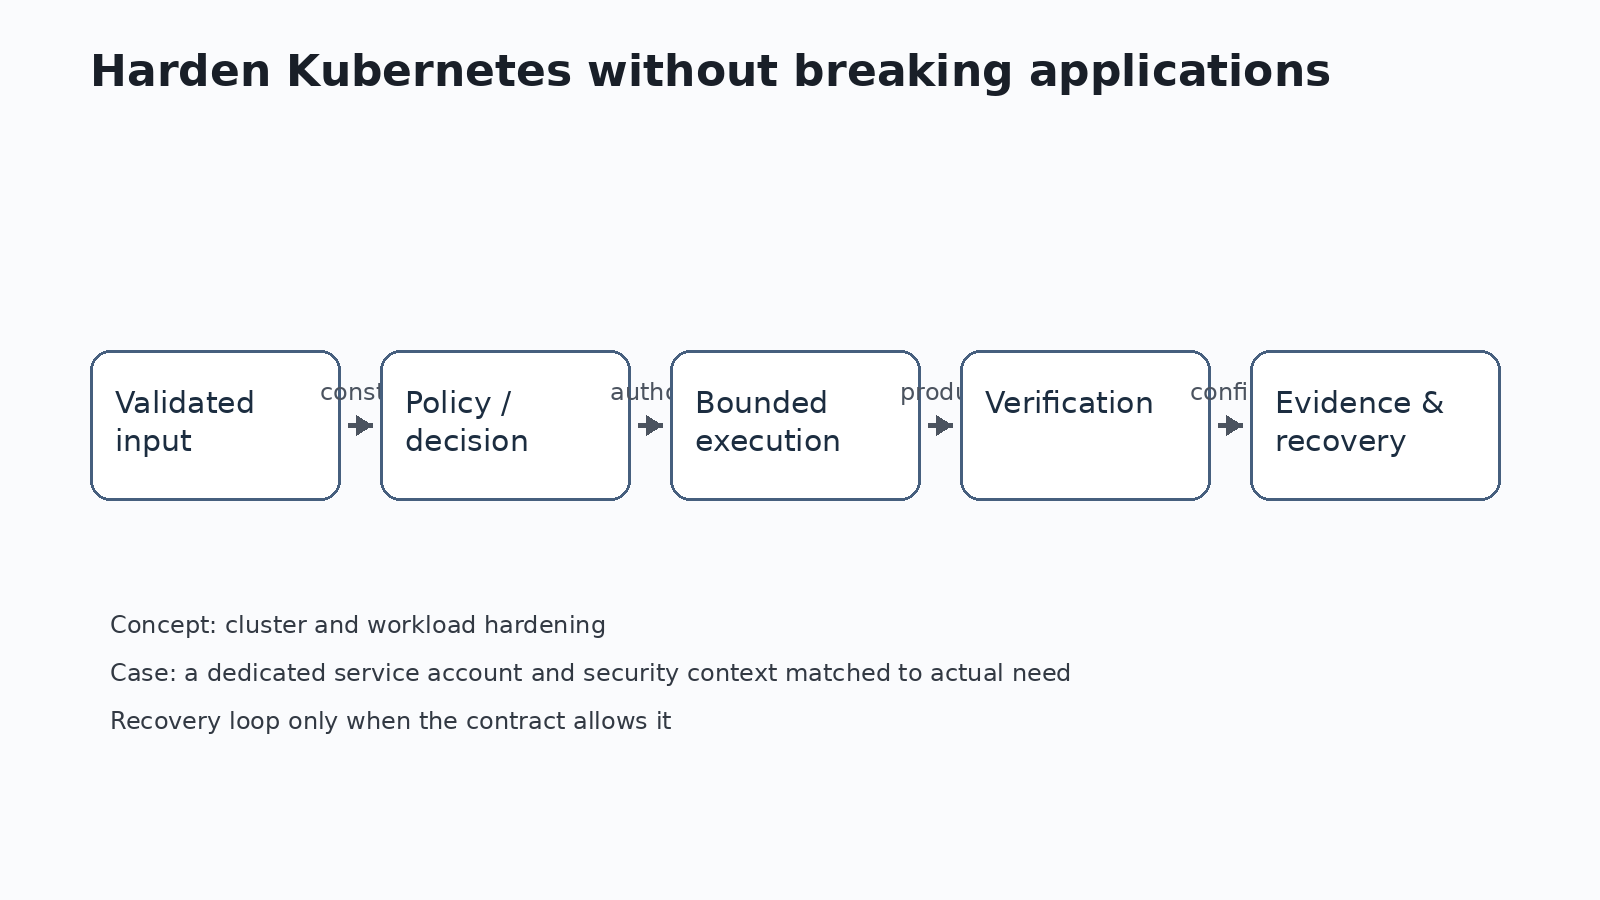
At the intermediate level, those rules become explicit interfaces. Inputs are validated before sensitive components are called; outputs are checked before they are persisted or propagated; external dependencies are wrapped behind stable boundaries. This lowers coupling and makes incremental evolution possible. A team can replace an implementation without rewriting the entire business journey when the contract remains stable and regression-tested.
At the intermediate level, those rules become explicit interfaces. Inputs are validated before sensitive components are called; outputs are checked before they are persisted or propagated; external dependencies are wrapped behind stable boundaries. This lowers coupling and makes incremental evolution possible. A team can replace an implementation without rewriting the entire business journey when the contract remains stable and regression-tested.
Advanced practice is mostly about observability and risk control. Logs should carry correlation identifiers, the minimum useful context, the decision taken, and the cause of failure without exposing unnecessary sensitive data. Metrics and traces are not substitutes for business reasoning. They should answer operational questions such as where the flow stopped, whether a retry is safe, and which component owns the next action.
In practice, a dedicated service account and security context matched to actual need must be testable end to end. Prepare a nominal case, incomplete data, an authorization denial, an unavailable dependency, and a repeated request. Define the expected result before running each test. This turns requirements into evidence and avoids validation that relies only on a screen looking correct or on the absence of an exception.
Practical decision checklist
Advanced practice is mostly about observability and risk control. Logs should carry correlation identifiers, the minimum useful context, the decision taken, and the cause of failure without exposing unnecessary sensitive data. Metrics and traces are not substitutes for business reasoning. They should answer operational questions such as where the flow stopped, whether a retry is safe, and which component owns the next action.
In practice, a dedicated service account and security context matched to actual need must be testable end to end. Prepare a nominal case, incomplete data, an authorization denial, an unavailable dependency, and a repeated request. Define the expected result before running each test. This turns requirements into evidence and avoids validation that relies only on a screen looking correct or on the absence of an exception.
The main trade-off often sits between immediate simplicity and future controllability. A queue, guardrail, approval gate, or additional layer has a cost. That cost is justified when failures are hard to detect, expensive to reverse, or capable of affecting people, data, or critical operations. Adding components without a matching risk, however, increases the failure surface and cognitive load.
An expert pitfall is to confuse automation with autonomy. Automating a known sequence is different from delegating an open-ended decision. For Harden Kubernetes without breaking applications, define what may execute automatically, what requires a deterministic policy, and what needs human confirmation. That classification should be visible in code, tests, and operating procedures rather than living only in a high-level document.



Comments
No published comment yet.
Sign in to comment